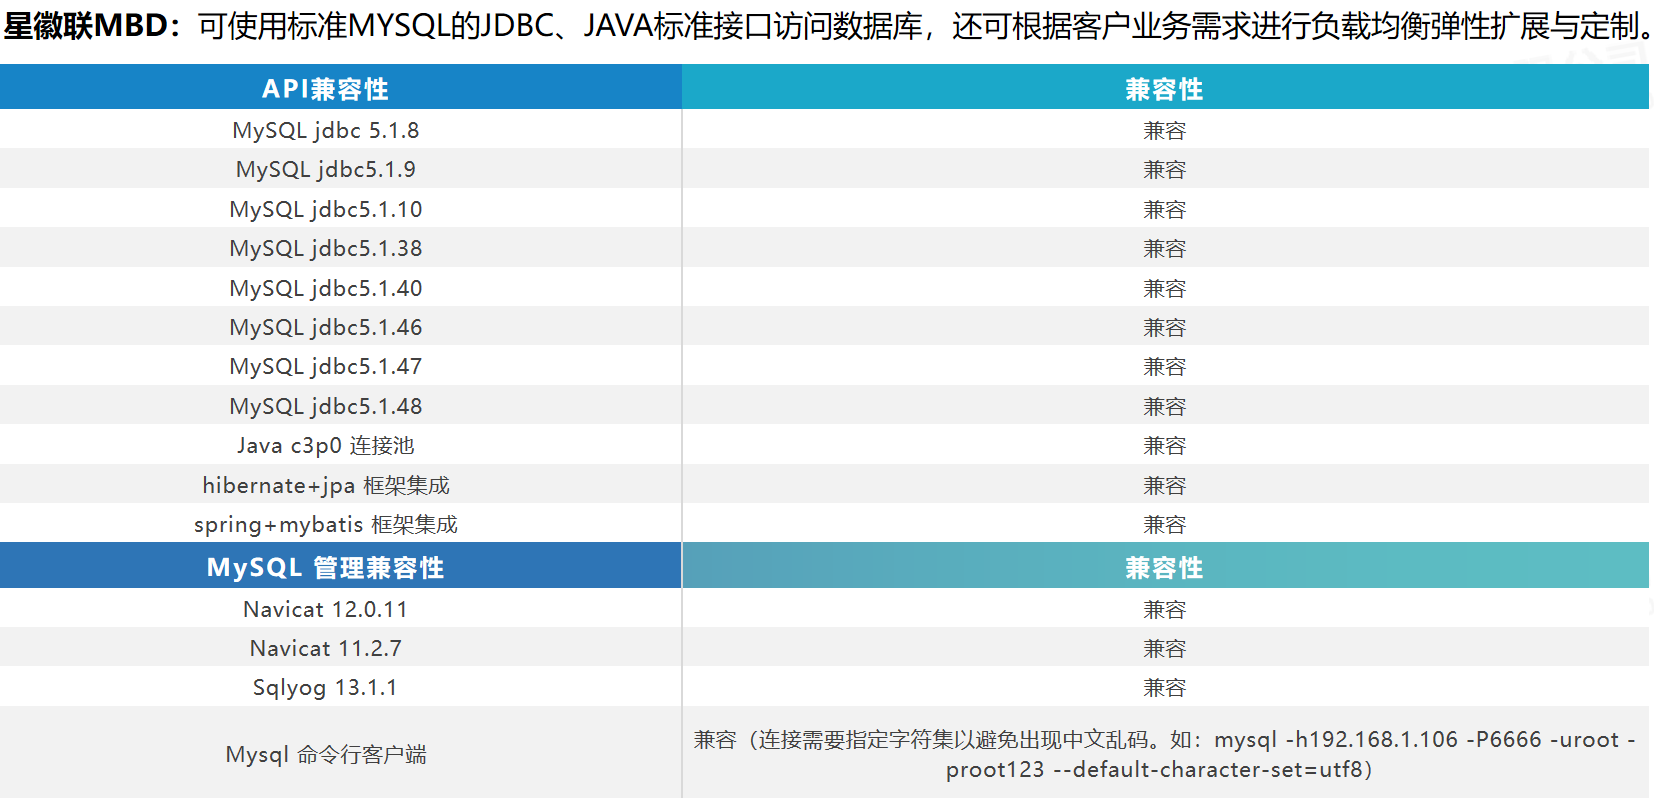
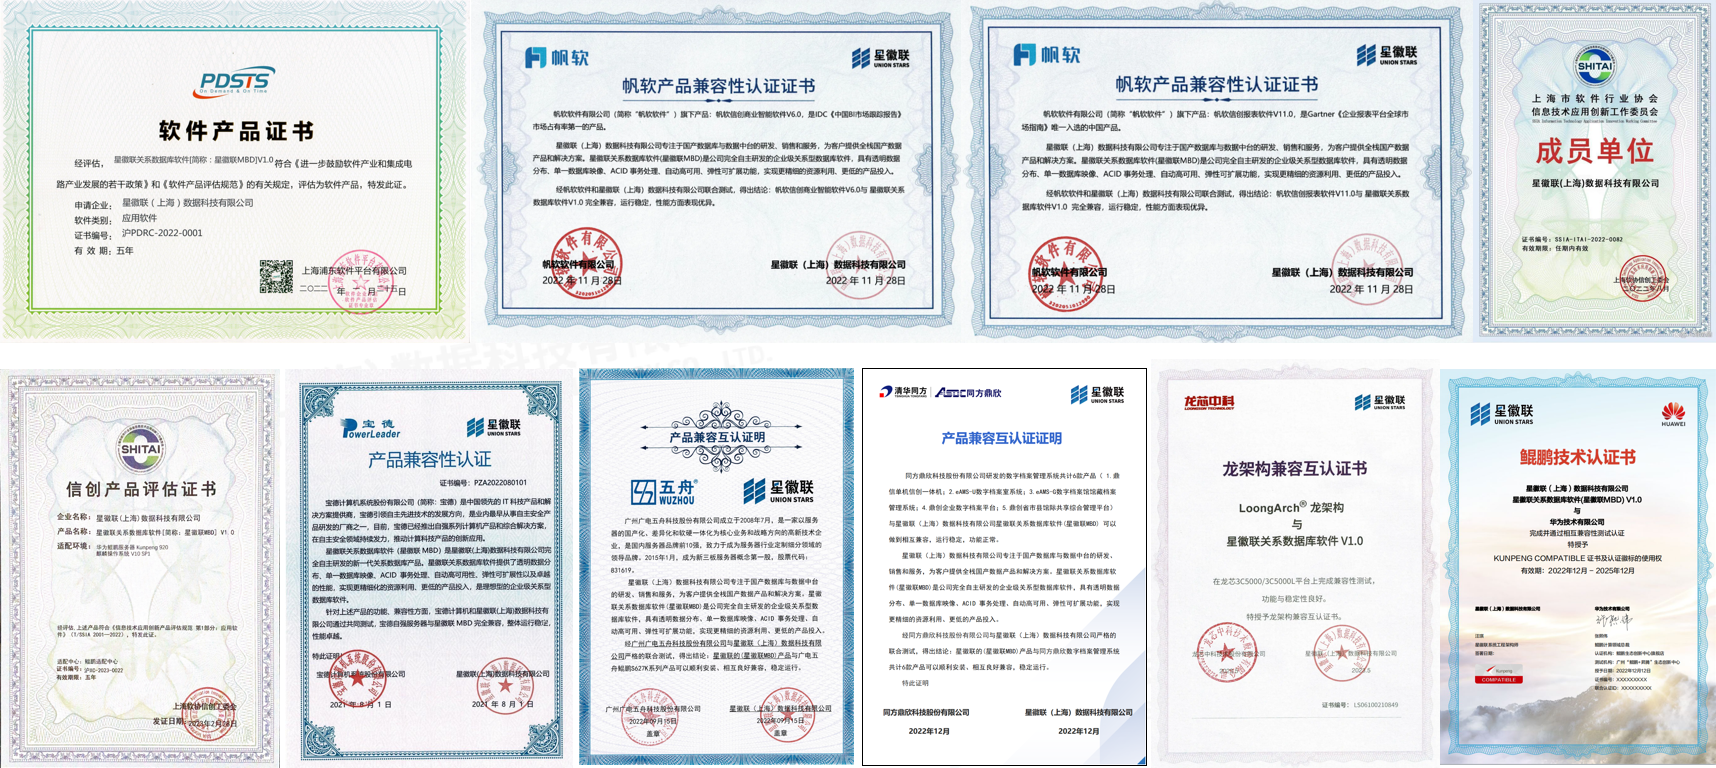
(1) This product employs a tiered data management strategy based on hot and cold partitioned data. It innovatively integrates an in-memory database architecture with a disk-based database for non-hot data, creating a cutting-edge data storage and access framework. This approach combines architectural advancement with application innovation, effectively addressing the high costs associated with clustered databases.
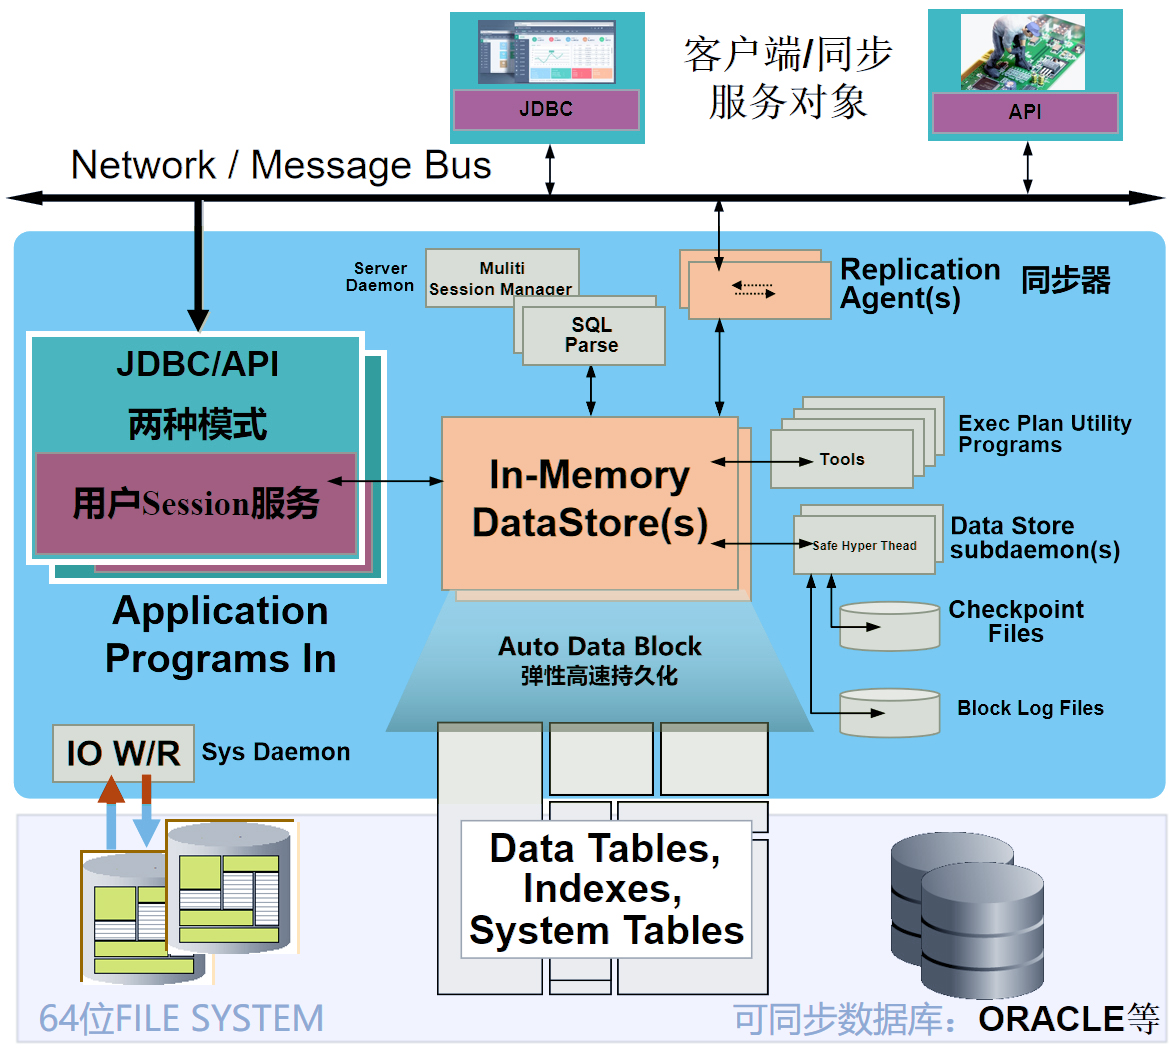
(2) Innovative patent-pending vertical sharding of data tables and in-memory indexing for differential engines decouples real-time workloads from slow I/O, resolving the core space-time trade-off in traditional database ecosystems. This achieves industry-leading decoupling of memory from compute/storage, enabling further memory pooling across multiple tiers and delivering order-of-magnitude improvements in system elasticity.
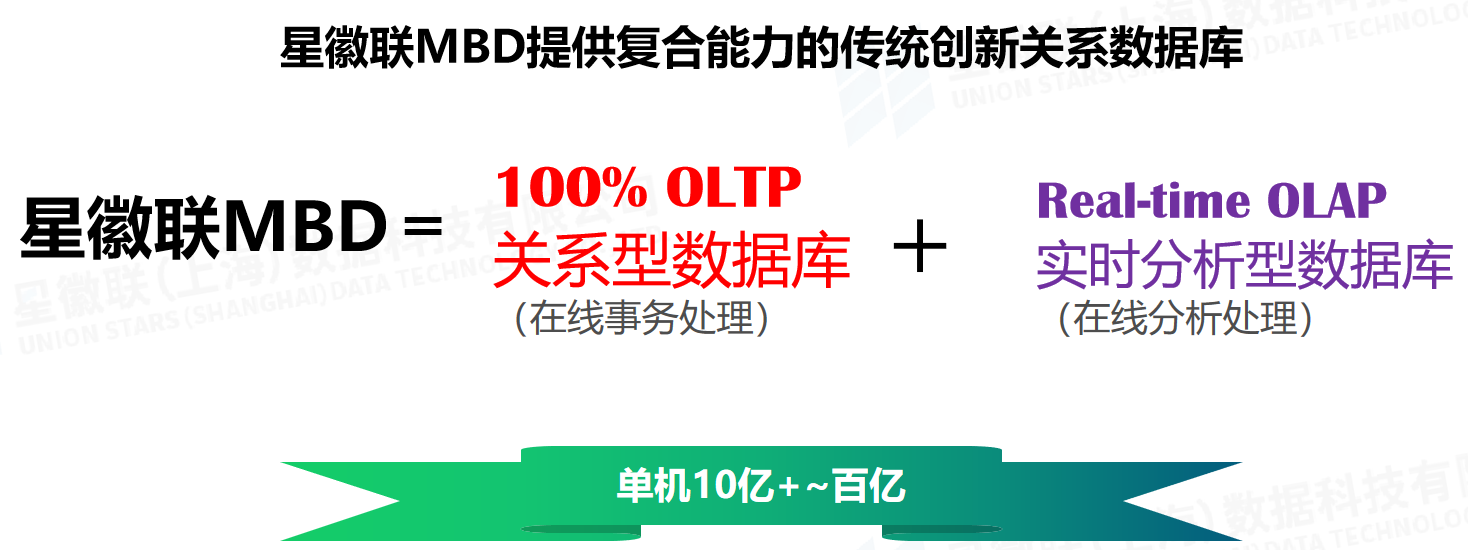
(Innovatively developed a differential engine technology using configurable memory data hot/cold aging and tiered separation. This enables massive single-table logical space to be managed via a unified mirror—supporting tens, hundreds, or even trillions of rows without sharding, while maintaining consistent performance at scale.)
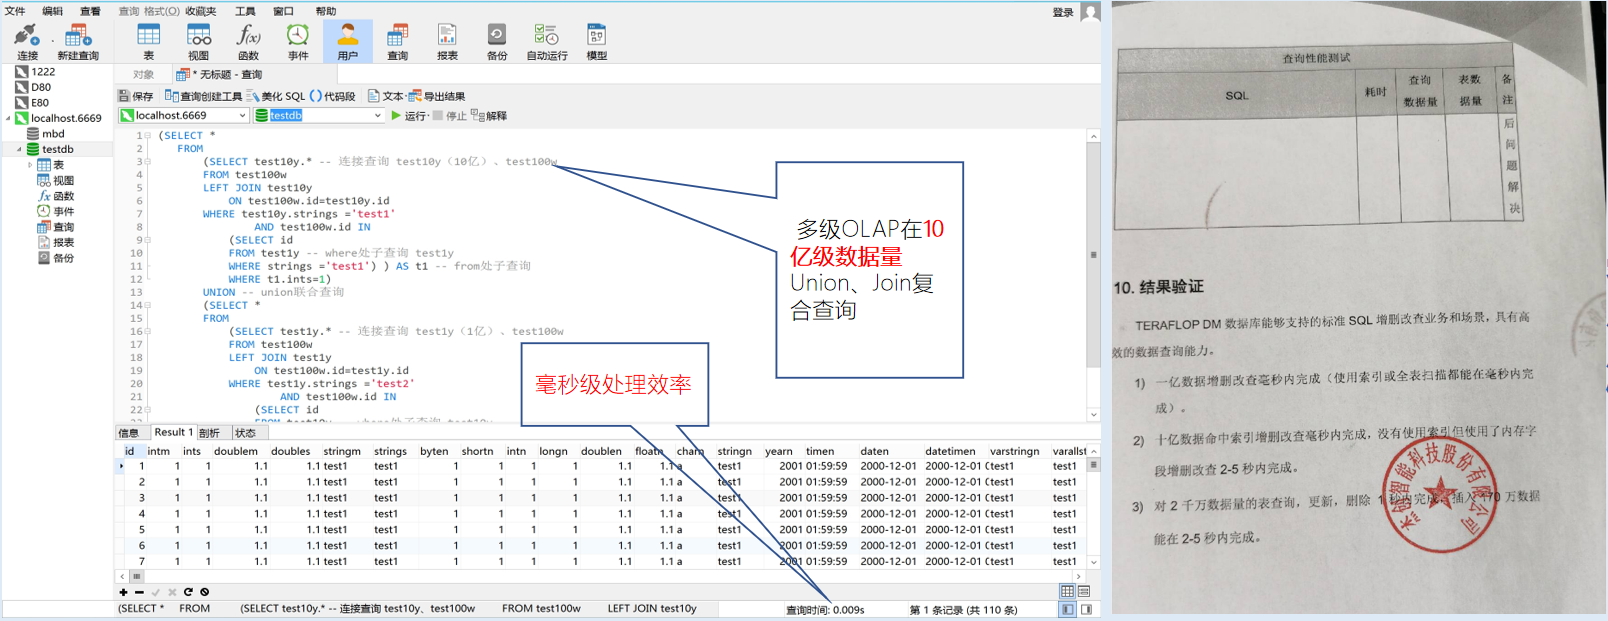
(4) Implements a new SQL Cost-Based Parallel Optimizer that leverages statistics and syntax cost analysis to determine the optimal execution plan. Provides full parallel operator support, including complex multi-level nesting, intersection/union joins, and large-scale union structures. Introduces load-adaptive capabilities for dynamic adjustments based on resource usage, such as falling back to serial execution or reducing parallelism.
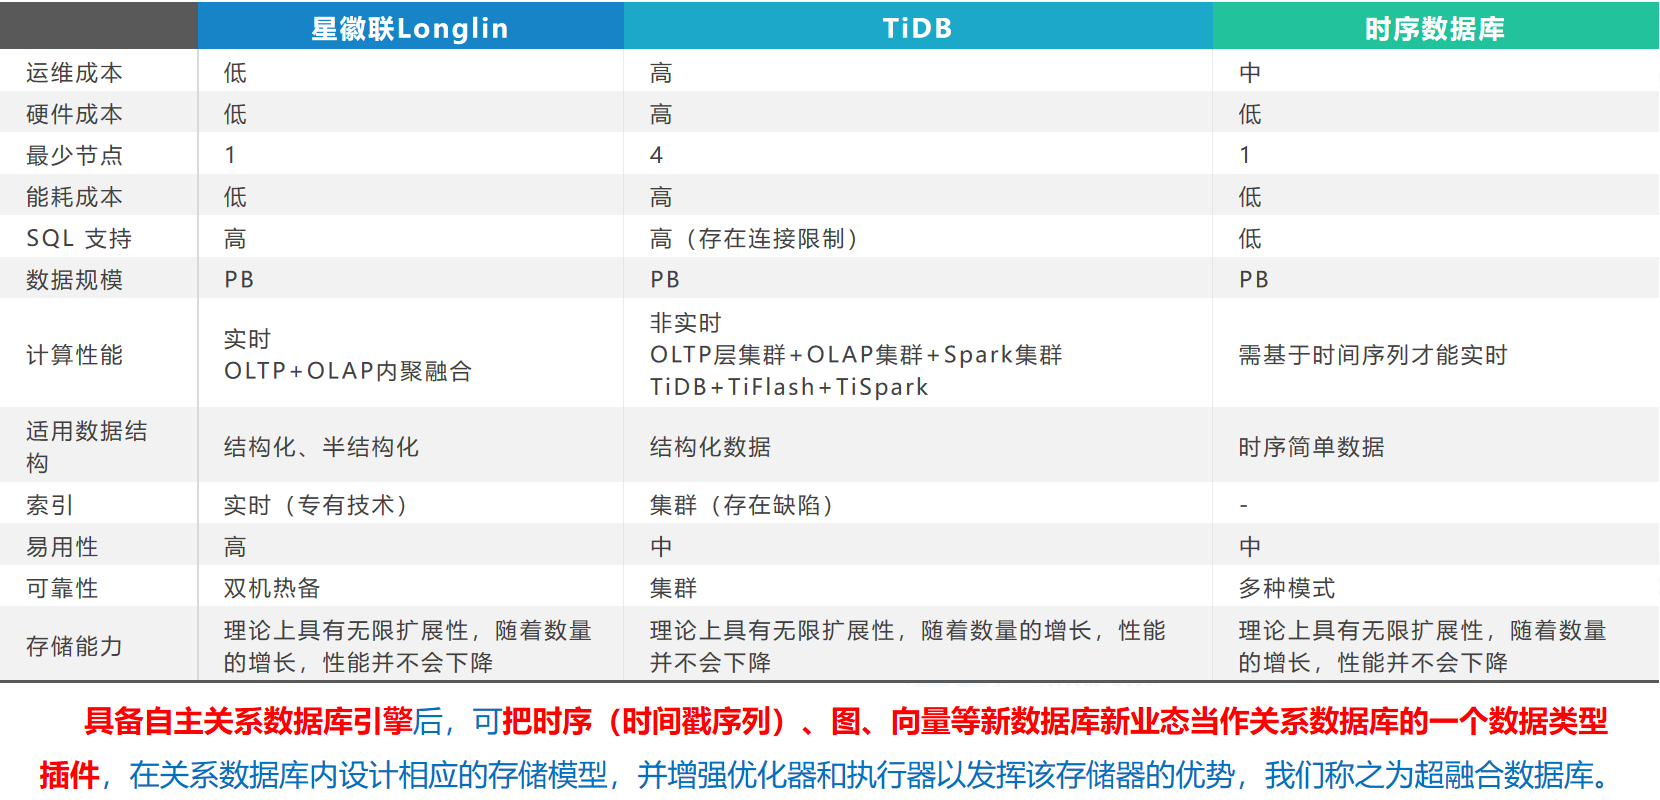
(5) Innovative autonomous indexing algorithm technology enables billion-scale data localization jump scanning within 30 iterations, fully independently implementing single and multi-level indexing, and achieving complete autonomous transaction closure.
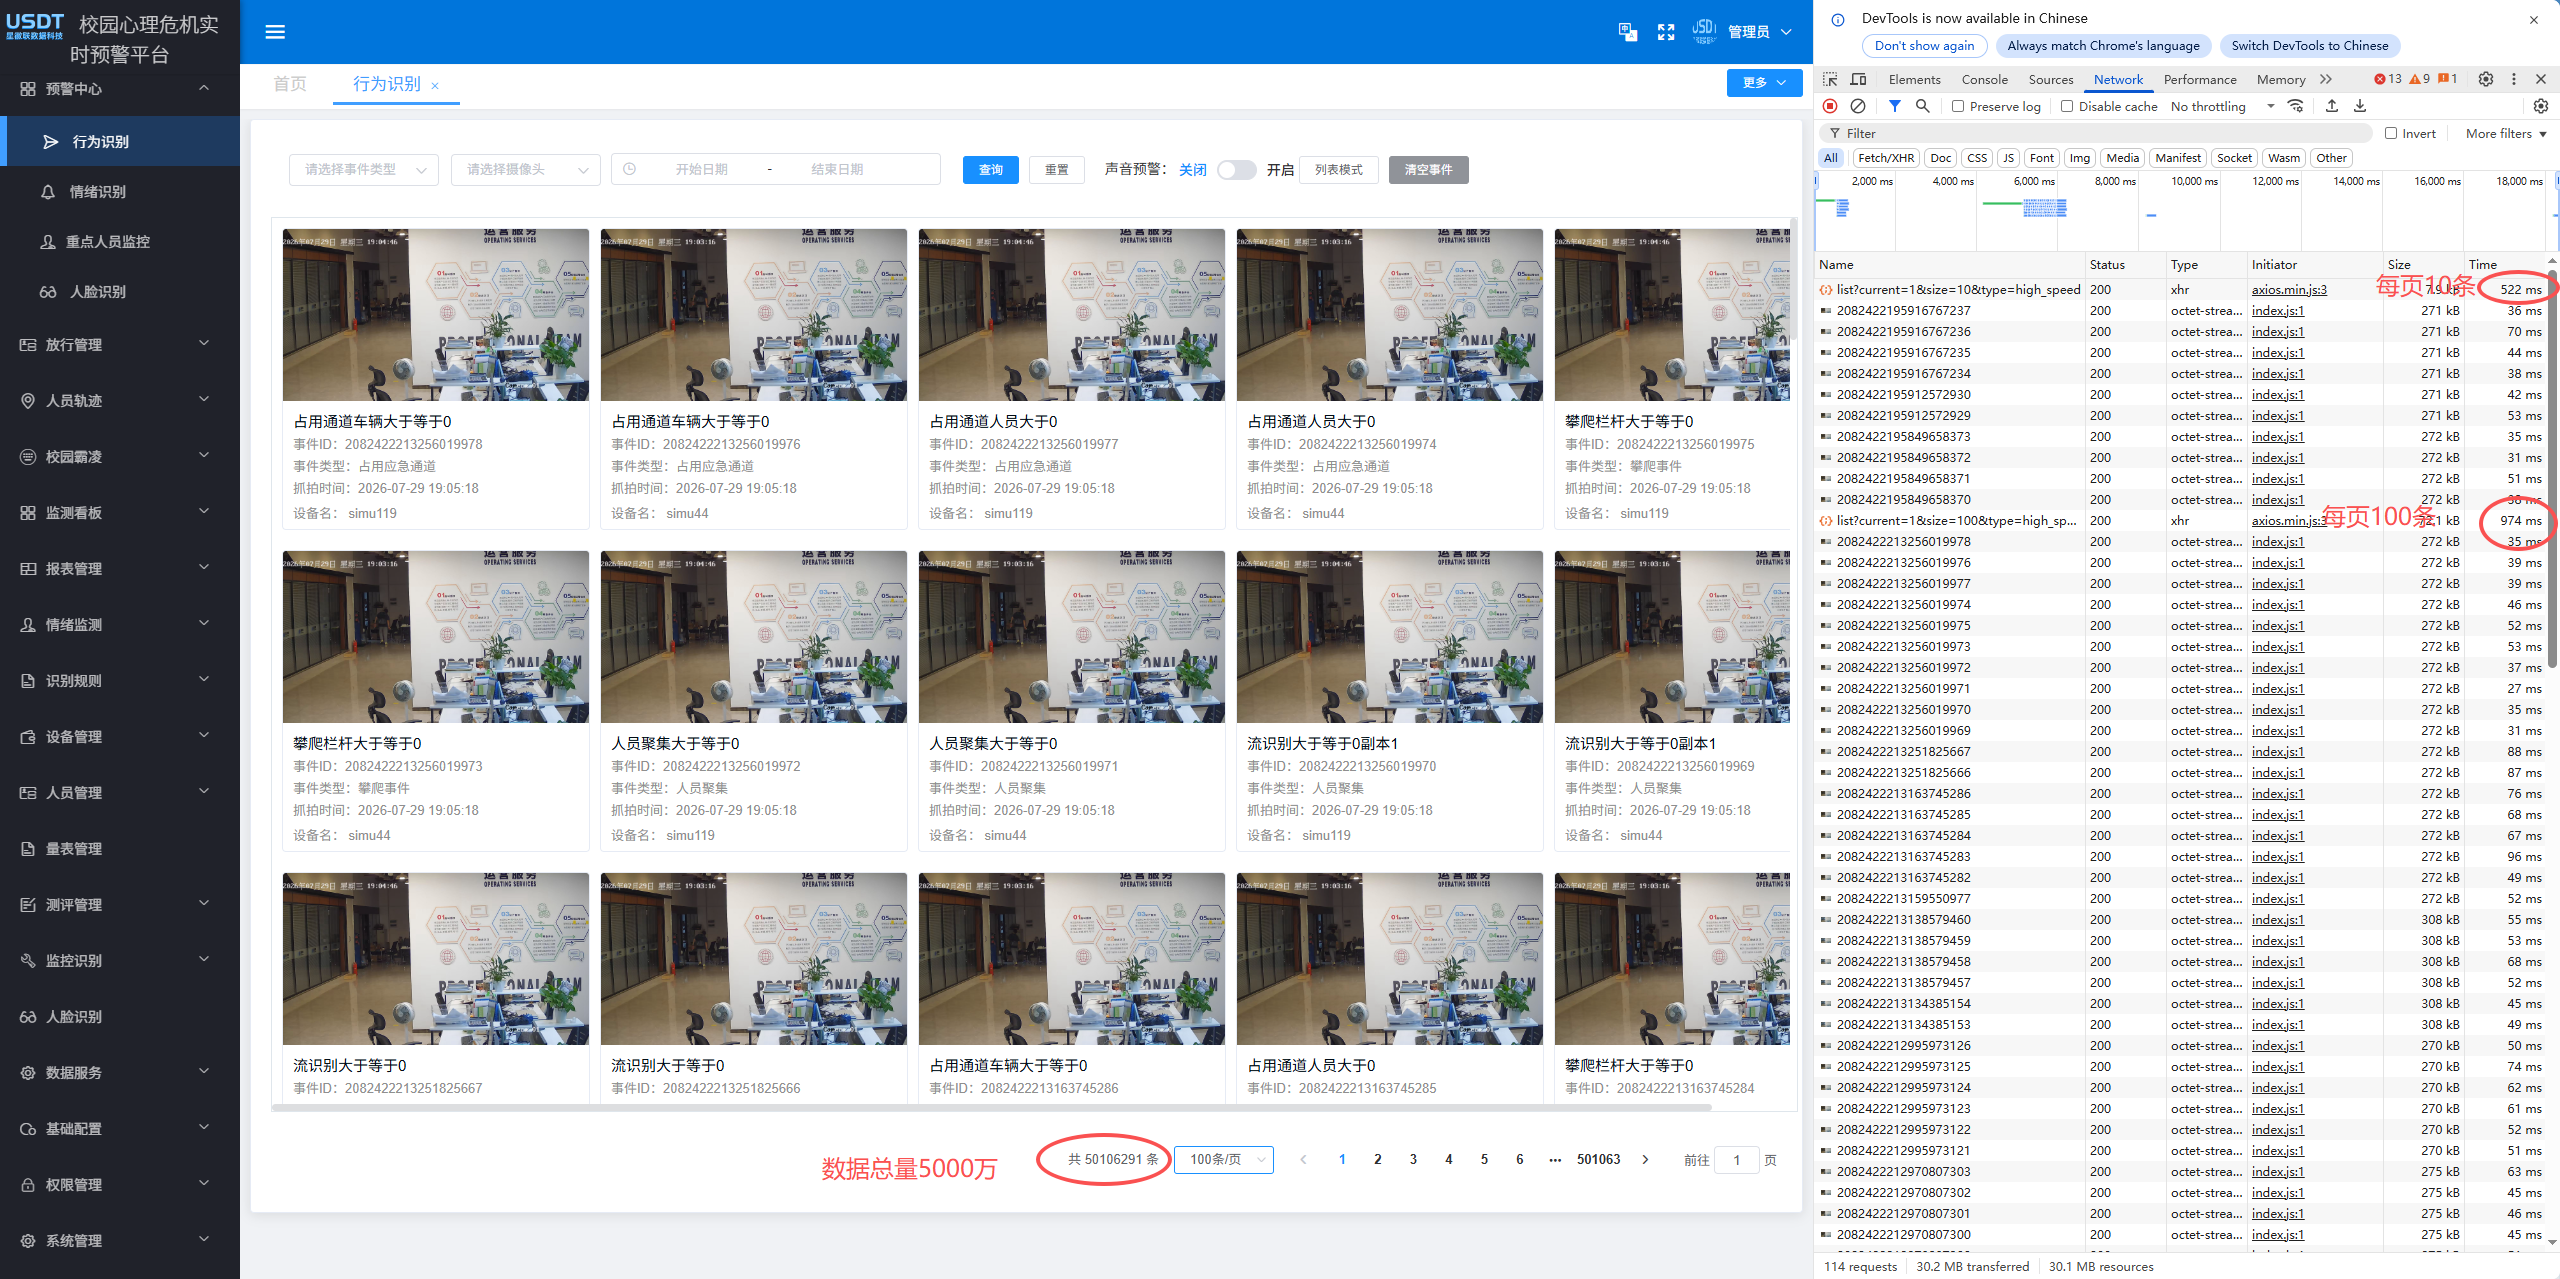
Pagination efficiency for 5000k review queries
The SQL is as follows:
SELECT id, aisle, event_type, status FROM bus_early_warn_result WHERE
is_deleted = 0
AND Create_time >= '2026-07-24 00:00:00' AND Create_time < '2026-05-25 00:00:00'
AND event_type IN ('rlsb01', 'ruqin', 'xiyan', 'FFRQ', 'YHJC', 'ZYXFCD', 'RYJJ', 'dajia', 'person', 'ppsj')
AND type != 'face'
(6) A fully self-developed domestic Java-based high-concurrency SQL query engine package. Built with JVM technology, it is a next-generation database engine delivering instruction-set and system-level cross-platform compatibility.